

TEASAR skeletonization of 3D label volumes on NVIDIA GPUs




Website · User guide · Benchmarks · C/C++ SDK · Changelog
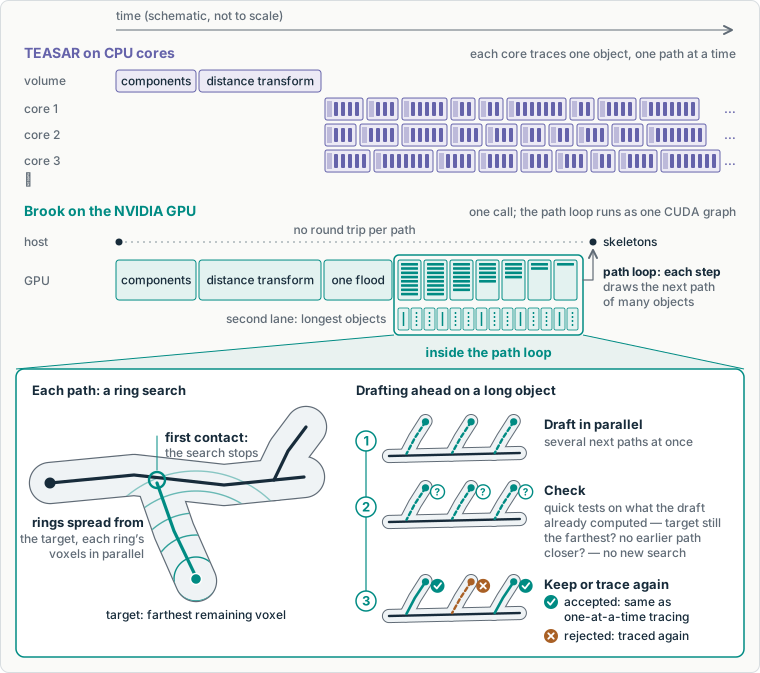
Schematic, not to scale.
Brook turns a 3D label volume, such as a neuron segmentation in connectomics, into one skeleton per object: vertices, edges and a radius at each vertex. Connected components, distance transforms, path tracing and, when memory allows, skeleton assembly run on the NVIDIA GPU. It is a C++17/CUDA library with Python, C and C++ interfaces.
brook.skeletonize takes the arguments of kimimaro.skeletonize and returns
osteoid.Skeleton objects (Kimimaro compatibility). On twelve
datasets, Brook on an NVIDIA RTX 4090 was 9.9× to 134× faster than Kimimaro 5.8.1 with 8
workers on 8 cores (Performance).
Platform: Linux x86-64; an NVIDIA GPU of compute capability 8.0 or newer (Ampere or later); an NVIDIA driver that supports CUDA 12.3 or newer. There are no macOS wheels, and Windows is untested.
python -m pip install brook-cu12Wheels cover Python 3.12 to 3.14 on Linux x86-64 and include the CUDA runtime, so you need only an NVIDIA GPU and driver (Requirements). For anything else, build from source.
Install one Brook package per environment; the import name is brook.
Runtime dependencies are NumPy, osteoid, tqdm and packaging (which fastremap, used by
osteoid, imports without declaring it). Optional extras: "brook-cu12[igneous]"
(experimental), [crackle], [profile].
import numpy as np
import brook

labels = np.load("labels.npy")  # 3D integer labels; 0 is background

# anisotropy: the voxel size, for example in nanometres
skeletons = brook.skeletonize(labels, anisotropy=(16, 16, 40))

for label, skeleton in skeletons.items():  # {label: osteoid.Skeleton}
    print(label, len(skeleton.vertices), skeleton.cable_length())
labels can also be a CuPy array or a PyTorch CUDA tensor, read without a copy to host memory.
Several volumes go through in one call:
result = brook.skeletonize_batch(volumes, anisotropy=(4, 4, 4))  # results stay on the GPU
first = result[0].to_skeletons()  # sample 0 as {label: osteoid.Skeleton}
examples/quickstart.py
runs without a data file. The user guide
covers TEASAR options, GPU input and output, batches, PyTorch, large volumes, Igneous and
environment variables.
- Kimimaro's interface: the arguments of
kimimaro.skeletonize, andosteoid.Skeletonobjects. - GPU in, GPU out: reads CuPy arrays and PyTorch CUDA tensors in GPU memory; packed results can stay there (CUDA array interface, DLPack).
- Batches:
skeletonize_batchtraces many independent volumes in one call, with the same result as separate calls. - PyTorch:
brook.contrib.torchhas forward-only functions and annn.Module. - Large volumes: streaming through GPU memory, or overlapping chunks on one or more GPUs.
- Igneous (experimental): an integration that runs existing Igneous
SkeletonTasks on Brook. - C and C++: a CUDA/C++17 library with C and C++ headers, a CMake package and pkg-config (SDK).
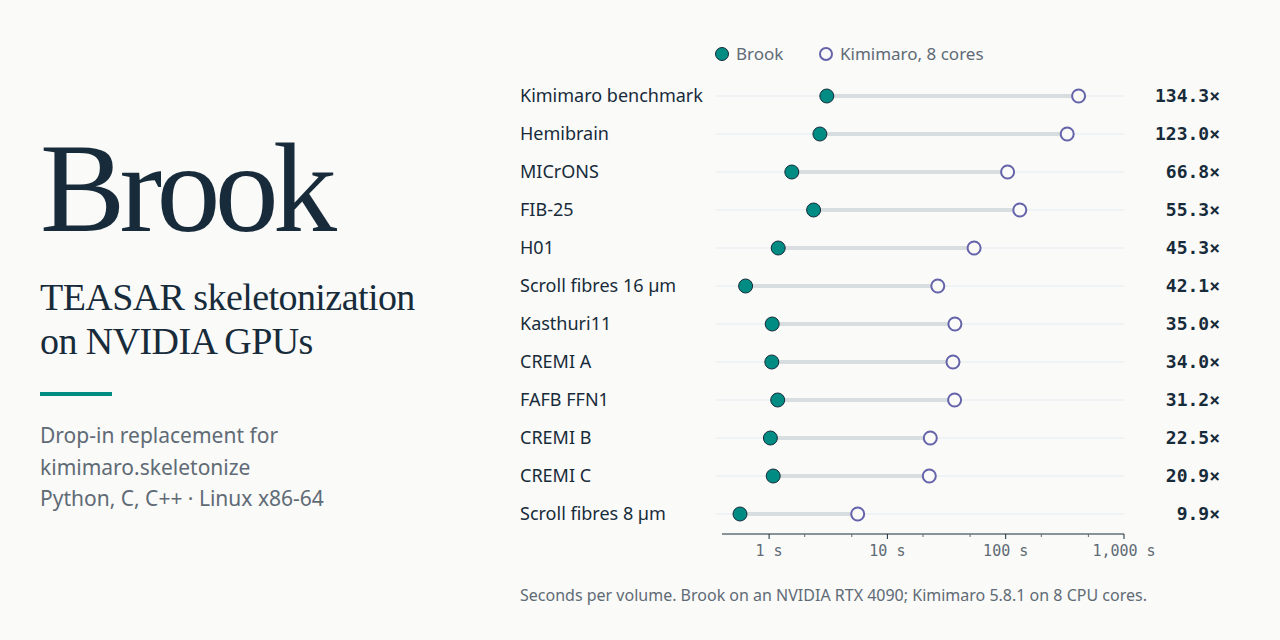
9.9× to 134× faster (median 38.5×), with the same labels in every case.
- Data: nine public electron-microscopy segmentations, two X-ray CT scans of papyrus fibres from a Herculaneum scroll, and Kimimaro's 512³ benchmark volume.
- Brook 0.1.0: one NVIDIA RTX 4090; median of three runs after one warmup.
- Kimimaro 5.8.1: 8 workers on 8 cores of an Intel Core i9-14900KF; one run each.
With 32 workers on the same CPU, the 512³ volume (branching correction on) took 415.1 s in Kimimaro and 3.115 s in Brook, 133.3× (medians of three complete calls after one warmup). Speed depends on object shapes, parameters, memory mode and the GPU. These runs use the in-core path; streaming needs less GPU memory and was not benchmarked. Full benchmarks · how to reproduce
Brook implements the TEASAR variant of Kimimaro and keeps its interface, so existing code changes one call:
- skeletons = kimimaro.skeletonize(labels, params, anisotropy=(16, 16, 40))
+ skeletons = brook.skeletonize(labels, params, anisotropy=(16, 16, 40))
On the tested volumes Brook returns the same objects (label IDs) as Kimimaro 5.8.1. The geometry is close but not identical, mainly for two reasons:
- Equal-cost routes. Where several paths have the same cost to float32 precision, Brook and Kimimaro can choose different ones. Brook tends to take straight axial steps where Kimimaro's order alternates between slices. Total cable length was 0.5% to 7.9% shorter in Brook across the twelve datasets under Performance; the largest differences were on the two scroll-fibre scans.
- Soma branches. For objects with a soma, Brook trims paths inside the cell body and attaches each branch to the soma root. Kimimaro 5.8.1 keeps more of those paths, so its skeleton of such an object can differ in shape and connectivity.
parallel is accepted and ignored; brook.GpuPool uses several GPUs. Details, including
fill_holes, fix_avocados and voxel graphs:
user guide.
| Component | Requirement |
|---|---|
| OS | Linux x86-64 (glibc 2.28 or newer for the wheels). There are no macOS wheels, and Windows is untested. |
| GPU | NVIDIA, compute capability 8.0 or newer (Ampere or later). Tested on an NVIDIA RTX 4090 (sm_89) and an NVIDIA H100 (sm_90). |
| Driver | R545 or newer, or R570 or newer where the driver JIT-compiles the PTX (a GPU without machine code in the wheel). Tested with drivers R570 and R615. |
| Python | CPython 3.12, 3.13 or 3.14 for the wheels; Python 3.12 or newer for a source build. Dependencies: NumPy, osteoid, tqdm, packaging. |
| CUDA | The wheels bundle the CUDA 12.8 runtime. A source build needs the NVIDIA CUDA Toolkit 12.3 or newer. |
Before it first uses a GPU, Brook checks its compute capability, the driver version and
whether the build has GPU code the driver can load; on an unsupported setup it raises
brook.device.CudaError that names the problem and the fix
(startup check).
If you use Brook in your work, please cite it (GitHub's "Cite this repository" button reads CITATION.cff):
@software{brook,
  author = {Angelotti, Giorgio},
  title = {Brook: TEASAR skeletonization on NVIDIA GPUs},
  version = {0.1.0},
  year = {2026},
  license = {GPL-3.0-only},
  url = {https://github.com/giorgioangel/brook},
  doi = {10.5281/zenodo.22947047},
}
The DOI 10.5281/zenodo.22947047 always resolves to the latest release; version 0.1.0 alone is 10.5281/zenodo.22947048.
Brook implements the TEASAR algorithm [1] as Kimimaro does [2]:
- M. Sato, I. Bitter, M. A. Bender, A. E. Kaufman and M. Nakajima. "TEASAR: tree-structure extraction algorithm for accurate and robust skeletons". In Proceedings of the Eighth Pacific Conference on Computer Graphics and Applications, Hong Kong, pp. 281–449. IEEE Computer Society, 2000. doi:10.1109/PCCGA.2000.883951
- W. Silversmith, J. A. Bae, P. H. Li and A. M. Wilson. Kimimaro: Skeletonize densely labeled 3D image segmentations, version 3.0.0. Zenodo, 2021. doi:10.5281/zenodo.5539913
Brook is authored by Giorgio Angelotti and licensed under GPL-3.0-only. Third-party
components keep their own licenses; see
NOTICE. Wheels include NVIDIA's CUDA
runtime, which is licensed under the NVIDIA CUDA EULA
(brook/licenses/nvidia/CUDA-EULA.txt), not the GPL.
Report bugs and ask questions in the issue tracker. See CONTRIBUTING.md for contributions and SECURITY.md for reporting security issues.