






I build systems that have to be right, not just impressive — eval harnesses, retrieval pipelines, graph models, and the guardrails around them. Every number here is reproducible from a clean clone; where one isn't, the repo says so.
 |
 |
 |
|
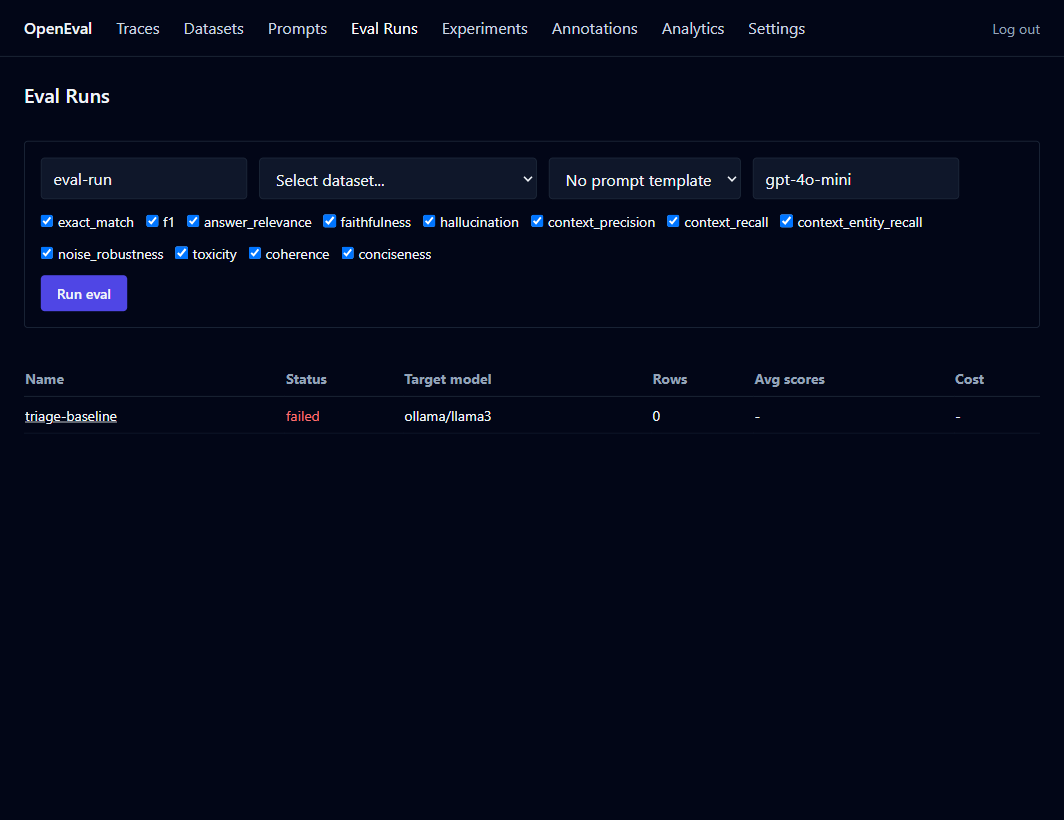
Self-hosted LangSmith alternative. 24 built-in evaluators, CI regression gate, one |
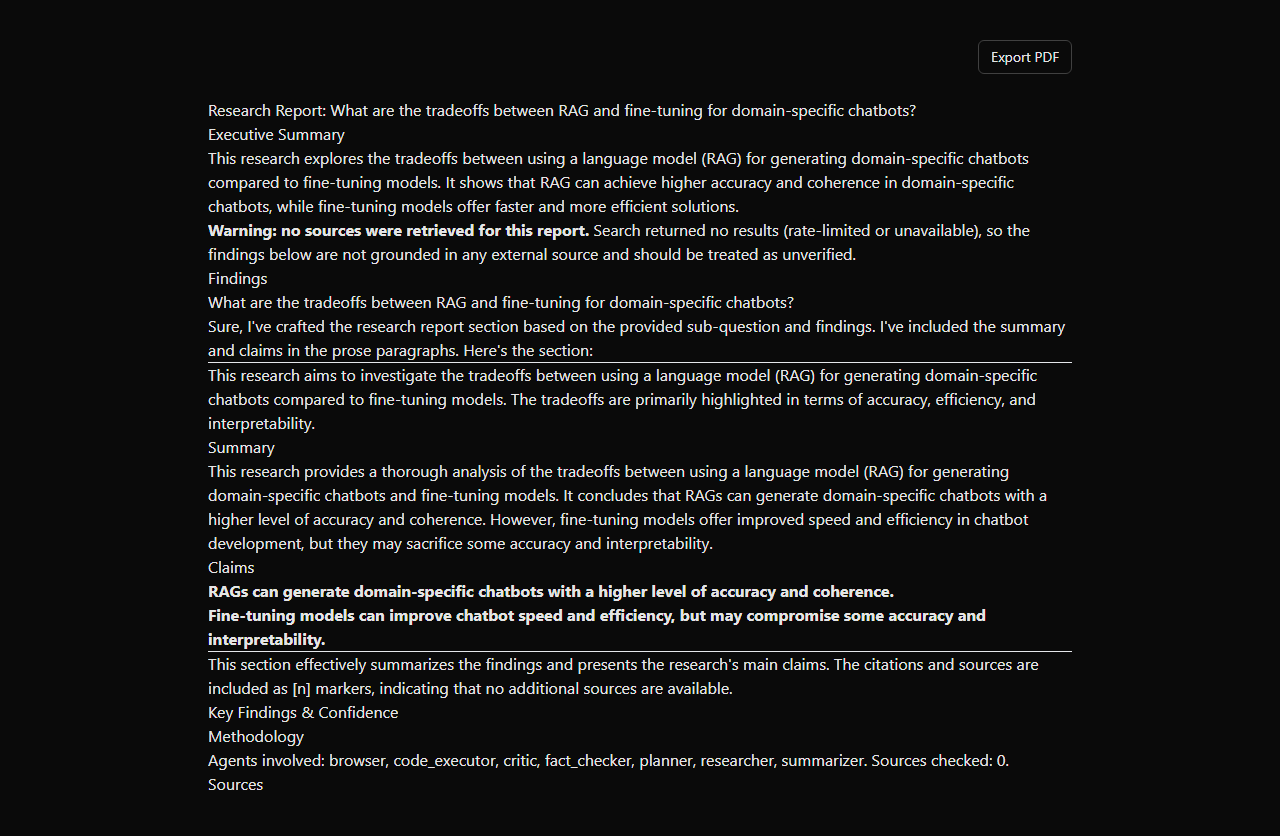
Nine LangGraph agents: plan sub-questions, search in parallel, cross-check every claim against ≥2 sources, return a cited report. Crash-resumes on another worker. Runs end to end on Ollama for $0. |
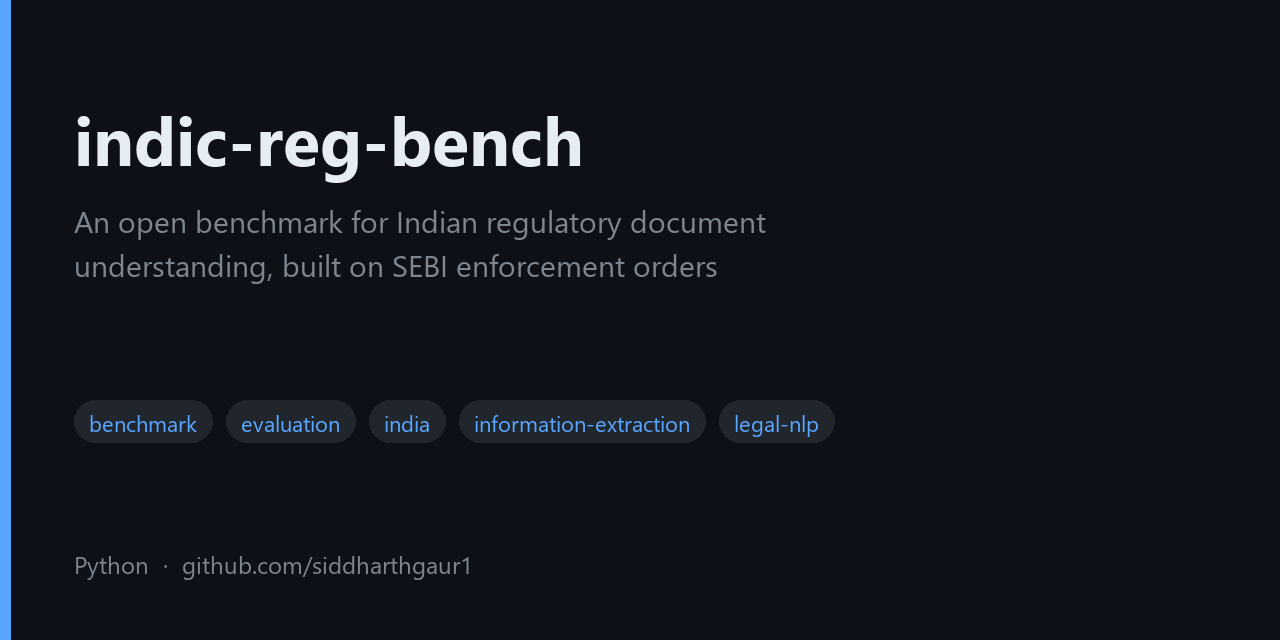
Open benchmark on 11,957 SEBI enforcement orders, plus a HF dataset. Tasks a regex can't win — the first currency amount in an order is the wrong answer 46.7% of the time. |
4 merged, 6 under review in other people's projects — MLflow (a Windows checkout shipped a wheel with zero Python files), Great Expectations ×2 (undefined SQLite stddev, mypy coverage), pdfplumber (blank exception messages). Under review: a DenseGATv2Conv layer for PyTorch Geometric, a pdfplumber cache fix (105 MB → 4.8 MB on a 65-page PDF), and four more.
Plus bugs found by probing libraries I use, reported with a reproduction: langgraph #8672, chroma #7735.
- elliptic-gatv2-aml — a published negative result: Random Forest (0.813 ± 0.005 illicit-F1 over 4 seeds) beats my GATv2 (0.213 ± 0.016) on every seed. The finding is that the fancy model lost.
- query-injection-bench — 226 attack cases that found a critical read-only bypass in my own Cypher guard, then measured the fix.
- recruit-voice-agent — the results doc separates fill rate from accuracy, names the latency target it missed, and labels every unrun measurement as unrun.
10 more projects — eval tooling, RAG, knowledge graphs, ML platforms, causal inference, MCP
| Project | What it does |
|---|---|
| llm-regressor | Regression testing for prompt and model changes; a reusable Action gates a PR in five lines. 100% branch coverage, ~2s, no API key |
| querypilot-v2 | English → SQL with schema-aware RAG. Write-safety is PRAGMA query_only plus an authorizer at the DB layer, so an injection that beats every earlier check still can't write |
| corpgraph-rag | Indian corporate network in Neo4j — GraphRAG question answering plus a GATv2 link predictor for relationships the filings don't state |
| ml-platform | Feature store, drift monitor and real-time fraud scoring merged so the train/serve seams are real imports, not duck-typed adapters. 113 tests |
| autonomous-data-scientist | A CSV and "predict churn" → 11 agents clean, tune, evaluate and report. Generated pandas runs through an AST whitelist into a locked-down subprocess |
| causal-lens | A/B testing (frequentist + Bayesian + CUPED), difference-in-differences, synthetic control, uplift modelling |
| indian-markets-mcp | MCP server, 8 tools, official sources only. Resolves the latest trading day against IST, so a UTC host doesn't report yesterday's close |
| nse-daily-monitor | Daily NSE bhavcopy checks against a trailing 60-day baseline, opening an issue when one fails. Derived metrics only, never a reconstructable quote |
| Sebi-Explorer · ▶ | Analytics over real public SEBI enforcement orders — the corpus problem that motivated indic-reg-bench |
| rail-graph · ▶ | A 600-station rail network as a graph: PageRank, betweenness, k-shortest paths, resilience simulation |
Demos run on free tiers, so an idle app first shows a wake button and takes ~40 seconds. Every one also runs locally from its repo's Quickstart with no API key.
Python · PyTorch · PyTorch Geometric · LangGraph · scikit-learn · XGBoost · FastAPI · Neo4j · PostgreSQL · Redis · Kafka · ChromaDB · Docker · GitHub Actions

Open to AI/ML roles — Mumbai or remote.
siddharthgaur200304@gmail.com ·
LinkedIn ·
Portfolio